menu email
AI-Powered Real Estate Document Classification

AI Document Classification for Real Estate at Scale

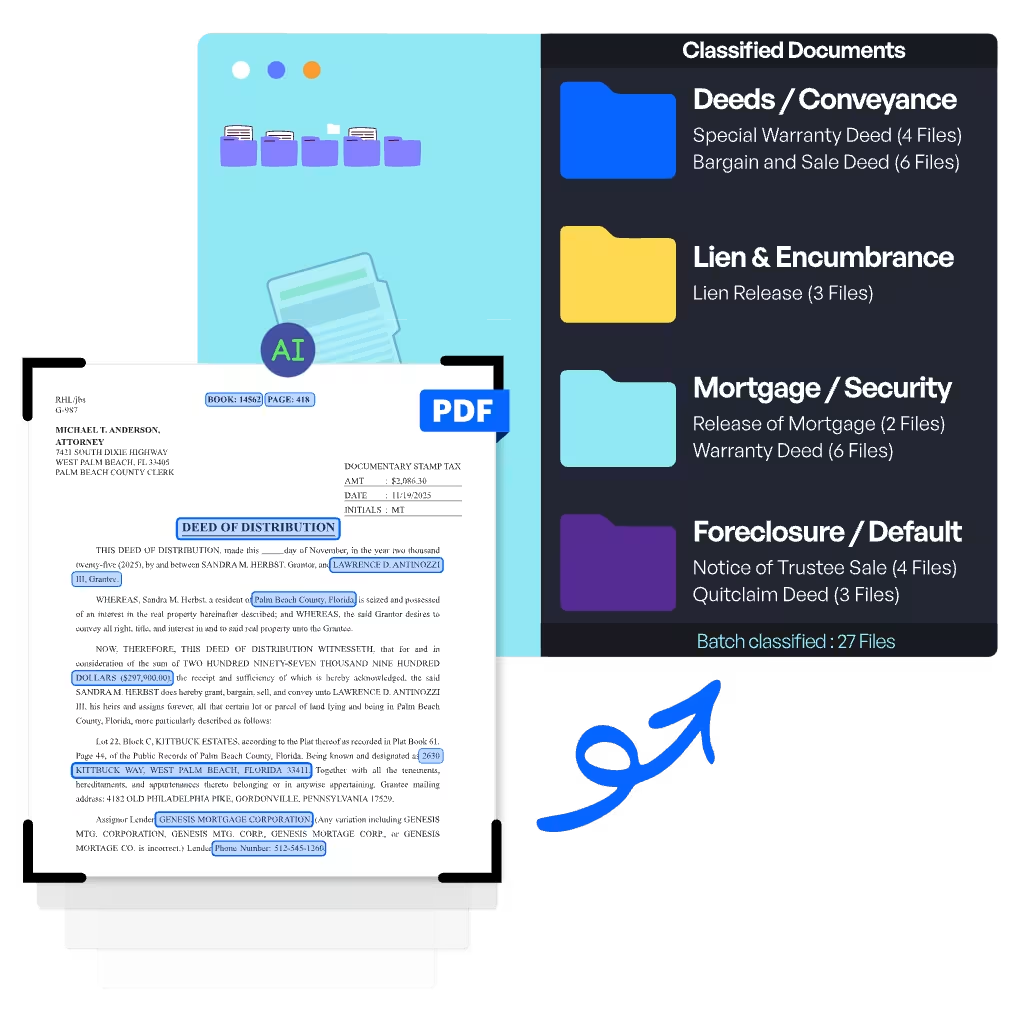
Automatically identify, separate, and classify real estate documents with domain-trained AI. Hitech i2i accurately classifies document type and sub-type for every deed, mortgage, lien, and recorded instrument before extraction, standardization, or validation begins.
Request a Free Sample Run
AI Document Classification for Real Estate at Scale

99%

Document Classification Accuracy

150+

Document Types Classified

60-70%

Reduction in Operational Costs

⟨  10

Seconds-Per-Document Classification

How Hitech i2i Tackles Document Classification Challenges

Real estate documents come from multiple systems in mixed, inconsistent formats and multi-instrument files. At scale, manual sorting and basic classifiers fail, leading to extraction errors and unreliable data.

Hitech i2i applies AI-based document classification purpose-built for real estate. It automatically categorizes documents into logical groups, accurately identifying document types and sub-types for rapid retrieval and downstream data extraction.

Key capabilities include:

  • Document Type Classification: Deeds, mortgages, liens, releases, assignments, affidavits.
  • Document Sub-type Classification: E.g., warranty deed vs quitclaim deed, original mortgage vs assignment.
  • Instrument-Level Separation within multi-document PDFs.
  • Upstream-system-agnostic processing across FTP, DMS, LOS, and title systems.
  • Confidence-based automation with human-in-the-loop escalation only when required.
How Hitech i2i Tackles Document Classification Challenges

Why Hitech i2i Wins in Real Estate Document Classification

We use advanced AI to classify real estate documents faster, more accurately, and at scale, helping businesses streamline workflows and reduce operational costs.

Domain-Trained AI Real estate-native AI trained on millions of property records. Start evaluating representative documents within 24 hours.
Precision Data Tagging Precision data tagging enables instrument-level intelligence beyond traditional file-level tagging.
Semantic Classification Context-aware classification uses legal language and jurisdictional patterns to distinguish legally distinct documents.
Scalable Automation Confidence-driven automation classifies 95%+ of real estate documents automatically by type and subtype, routing only low-confidence or ambiguous cases for targeted human validation

How Automated Document Classification Works

We use AI-powered document classification to automatically organize, categorize, and process documents, saving time and reducing errors.
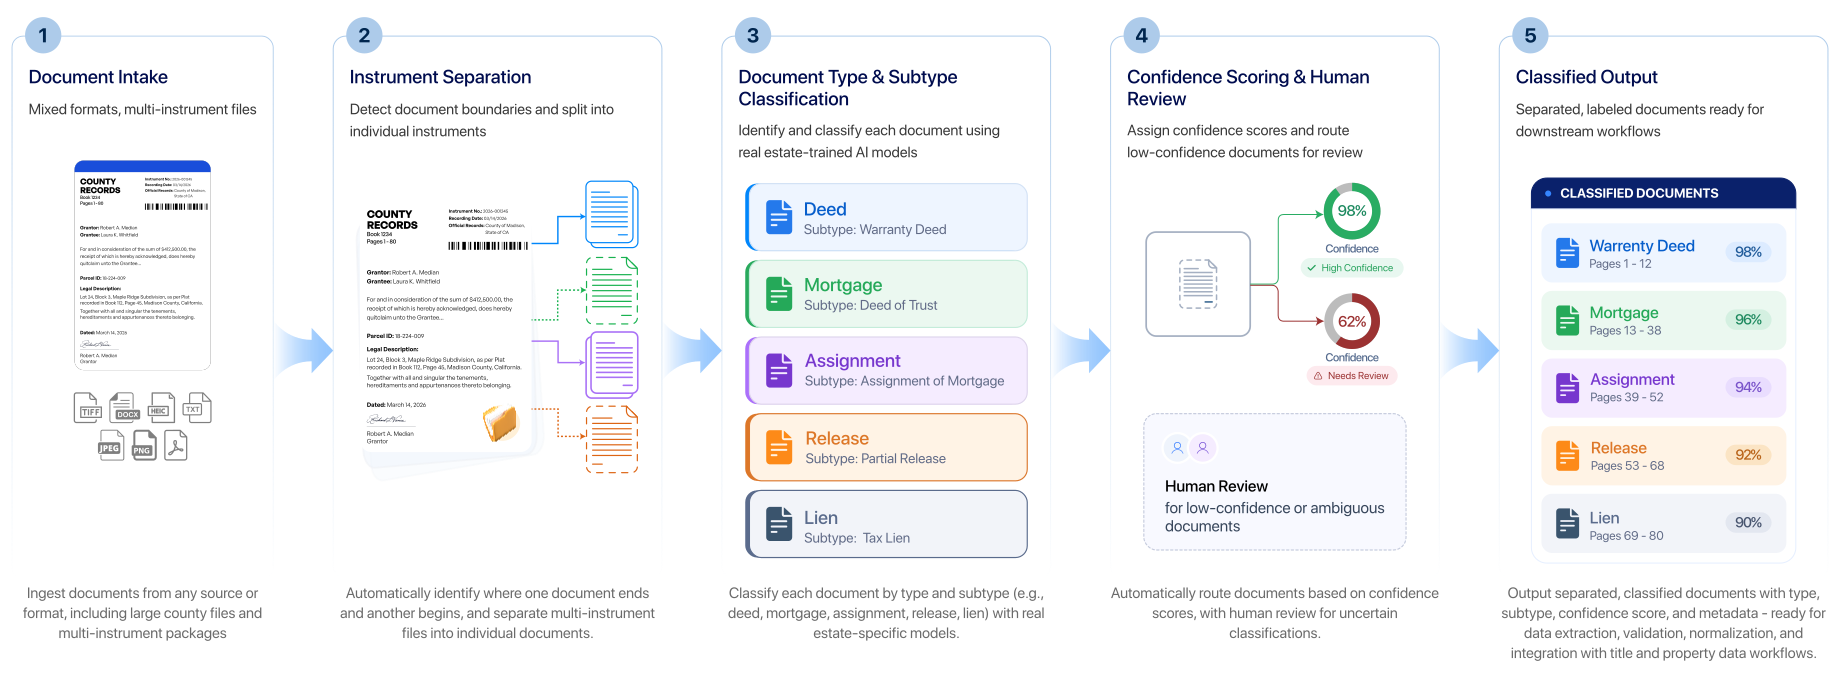
Automated Document Classification Works

Types of Real Estate Documents We Support

We handle a wide range of real estate documents, from contracts and leases to property deeds and inspection reports, ensuring fast and accurate classification.

Primary Types

Common Sub-Types

How a New York–based real estate marketplace automated property document classification with Hitech i2i

Property records from multiple counties included inconsistent formats, poor scans, and overlapping document categories. Hitech i2i deployed AI classification with confidence scoring and human review to accurately categorize documents at scale.

50,000

property documents classified daily

<5%

of documents required human review

Recommended Reading

Frequently Asked Questions

Does Hitech i2i acquire or scrape documents?
+
Hitech i2i can classify documents supplied by the customer or work within a broader managed workflow where required documents are sourced before classification. Source acquisition is supported using Hitech’s internal sourcing tools and agreed public-record or commercial sources, depending on the workflow.
Which upstream systems can Hitech i2i accept documents from?
+
Hitech i2i supports intake from FTP/SFTP, document management systems, title platforms, loan origination systems, servicing systems, and internal repositories.
Can Hitech i2i classify historical or legacy documents?
+
Yes. Hitech i2i is designed to handle historical and legacy property records, including older scanned documents, where structure and formatting may be inconsistent.
Can classification align with our internal taxonomy?
+
Yes. Document types and sub-types can be configured to match your internal framework.
What accuracy can be expected on historical scanned documents?
+
Hitech i2i applies advanced preprocessing techniques such as deskewing, noise removal, and contrast enhancement before classification. This helps maintain high accuracy even when processing 20–40-year-old scanned county property records.
How does Hitech i2i handle county-specific document variations?
+
Hitech i2i is trained on jurisdictional variations across counties and states. Its models recognize regional differences in document layout, terminology, and recording conventions and continuously adapt as new formats are introduced.
Is document classification configurable by client or use case?
+
Yes. Document type and sub-type taxonomies can be customized to align with your internal systems, business rules, or downstream workflows.
How are multi-document PDFs handled?
+
Each instrument is detected and classified independently using page-level analysis.
What happens when classification confidence is low?
+
Documents below a configurable threshold are routed for human review through built-in HITL workflows.
Can classification results be audited or reviewed later?
+
Yes. Every classification decision includes confidence scores and audit trails, enabling review, compliance validation, and historical analysis.
What is the ROI of automated document classification?
+
Automated classification significantly reduces manual document handling and processing costs. Hitech i2i can automatically classify 95%+ of real estate documents by type and subtype, with low-confidence or ambiguous cases routed for targeted human validation. This reduces manual sorting while preserving review controls for exceptions.
How does Hitech i2i handle ambiguous documents during classification?
+
Hitech i2i uses legal language patterns, instrument relationships, and confidence scoring to identify ambiguous documents that may appear structurally similar but are legally different. Instead of misclassifying them, the system automatically routes low-confidence cases to Human-in-the-Loop (HITL) validation, ensuring accuracy while maintaining high automation rates.

See Hitech i2i Classify Your Documents – Free Sample, 48-Hour Turnaround

Share a sample of your property documents and see how Hitech i2i classifies, extracts, and structures data with high accuracy.

Book a 15-Min Demo

SOC 2 Type II Certified | GDPR-compliant | No contract required | Your data stays secure | Results in 48 hrs